~/local-llm $ cat local-llm.md
Local LLM Enthusiast
 DGX Spark
 RTX Pro 6000
RTX 3090
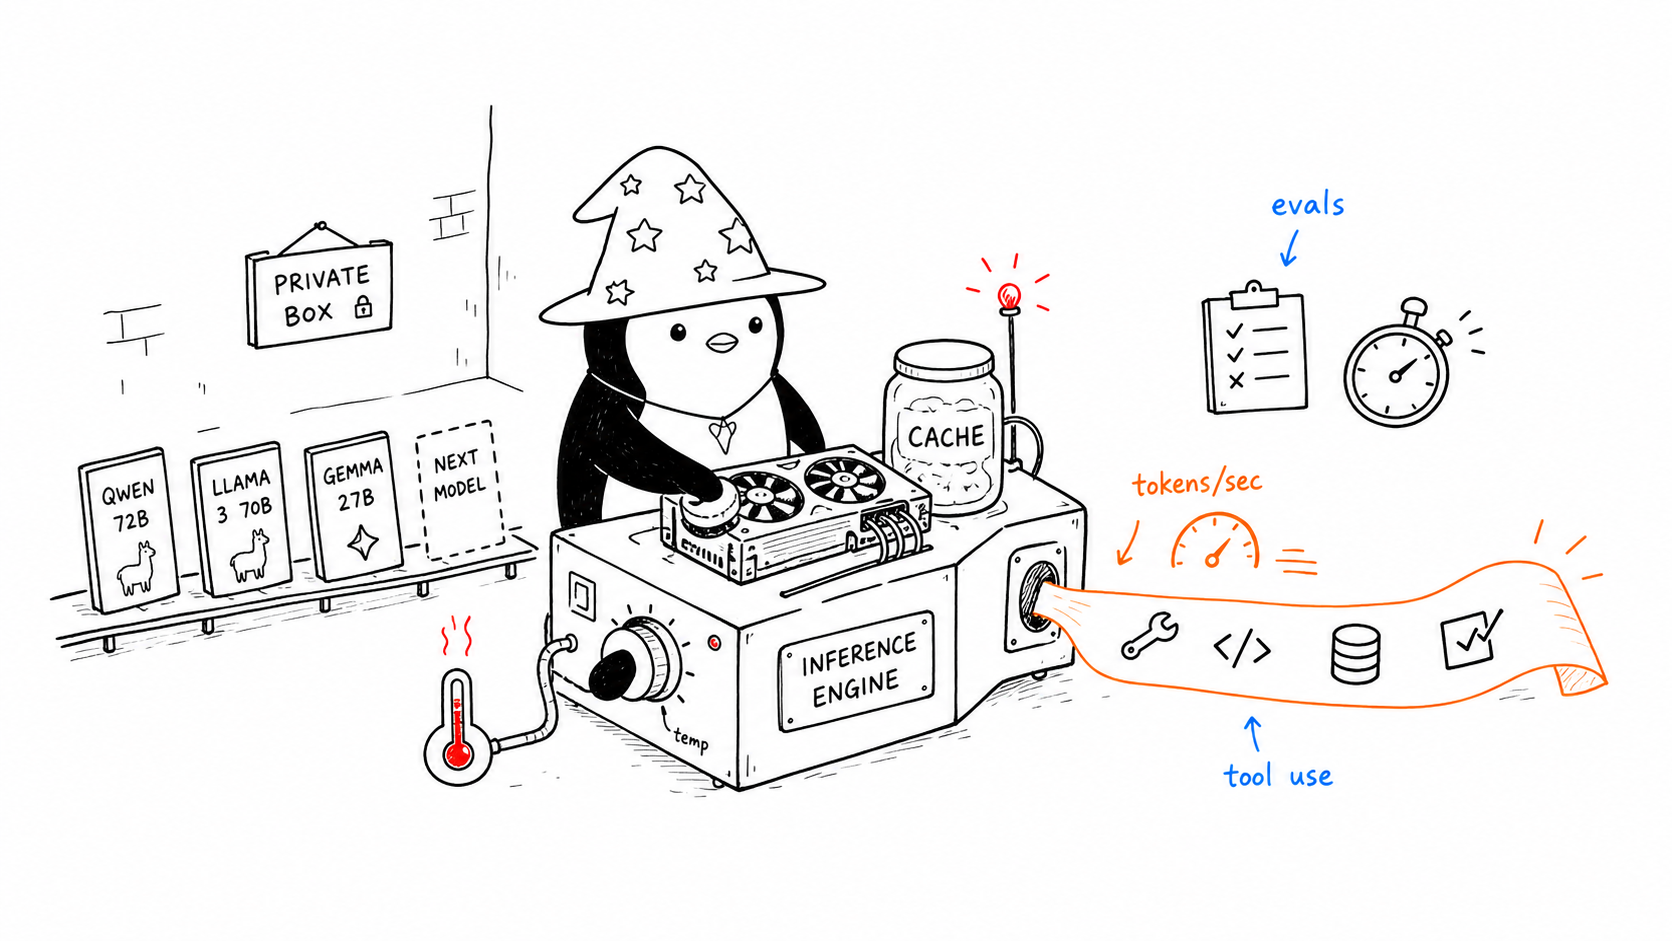
I run local LLMs on my own GPUs. Private data stays private, latency stays low, and the bill doesn’t grow with every token. What I care about is whether a model works for a real team: how fast it runs, how it scores on evals, and whether its tool calls hold up.
What I work on
- Serving models with
llama.cpp,vLLMandSGLang - Fine-tuning open models such as Qwen, Gemma, Llama and Pi.dev variants
- Evals with
lm-evaluation-harness,evalplusand my own benchmarks - Tuning quantization, batching and the KV cache for throughput
- Hooking local models up to agent tools, RAG pipelines and coding workflows
Selected work
- Unbound and Decision Model V1, a set of Jev-style decision models, fine-tuned and released on Hugging Face.
- DFlash support for Blackwell consumer GPUs in Luce.
- Bonsai benchmarks on a DGX Spark (GB10).
- A local Qwen model doing junior-dev work inside my agent workflows.
If your team needs private inference or help designing a local LLM workflow, start with my Forward Deployed Engineer page.